
NEW YORK, NY, October 20, 2026 (EZ Newswire) — Rehearsals, the leading platform to predict marketing outcomes by simulating AI twins of real people, launched Human Behavior Bench in partnership with Google DeepMind and Kaggle. It is the first public benchmark to determine how well an AI model is able to predict and understand human preference and action.
Looking at where AI development is headed, coding and task completion-based agents are a nearly solved problem but alignment to humanity’s values is far off. When OpenAI, Anthropic, Google and SpaceXAI launch a new model, there hasn’t been a public benchmark that determines a model’s understanding of humanity, until today.
“The industry focus of 2026 in AI was agents that complete long running tasks and mastering software engineering. Our bet for 2027 and beyond is a re-focus on values and cultural alignment to humanity as AI becomes more personal. This is the reason we co-created Human Behavior Bench with Google DeepMind,” said Liam Bolling, CEO and co-founder of Rehearsals.
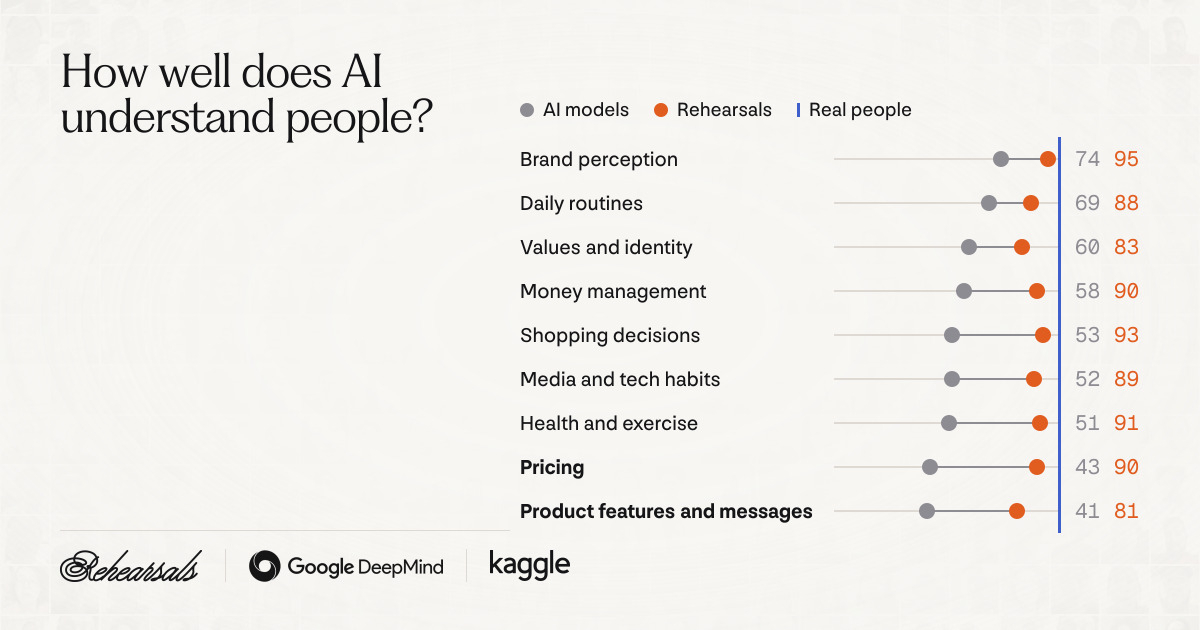
This initial version of the benchmark was created using Rehearsals’ human research platform to collect interviews of 1,244 U.S. adults across 750 categories with 95,000 responses and an 80% private holdout group. At a high level, the benchmark exposed that today’s state of the art AI models miss critical categories of human understanding: health, habits, decision making and values.
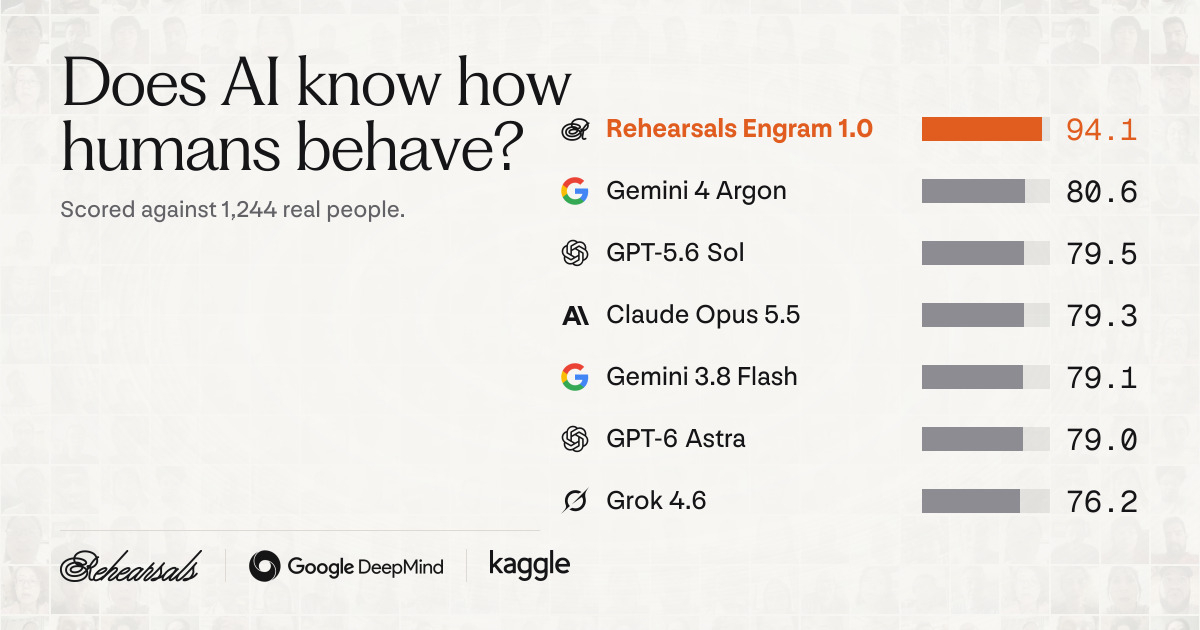
Here are the raw model results
Prediction System — Distribution Agreement (0 to 100):
- Rehearsals Engram 1.0: 94.1
- Gemini 4 Argon: 80.6
- GPT-5.6 Sol: 79.5
- Claude Opus 5.5: 79.3
- Gemini 3.8 Flash: 79.1
- GPT-6 Astra: 79.0
- Grok 4.6: 76.2
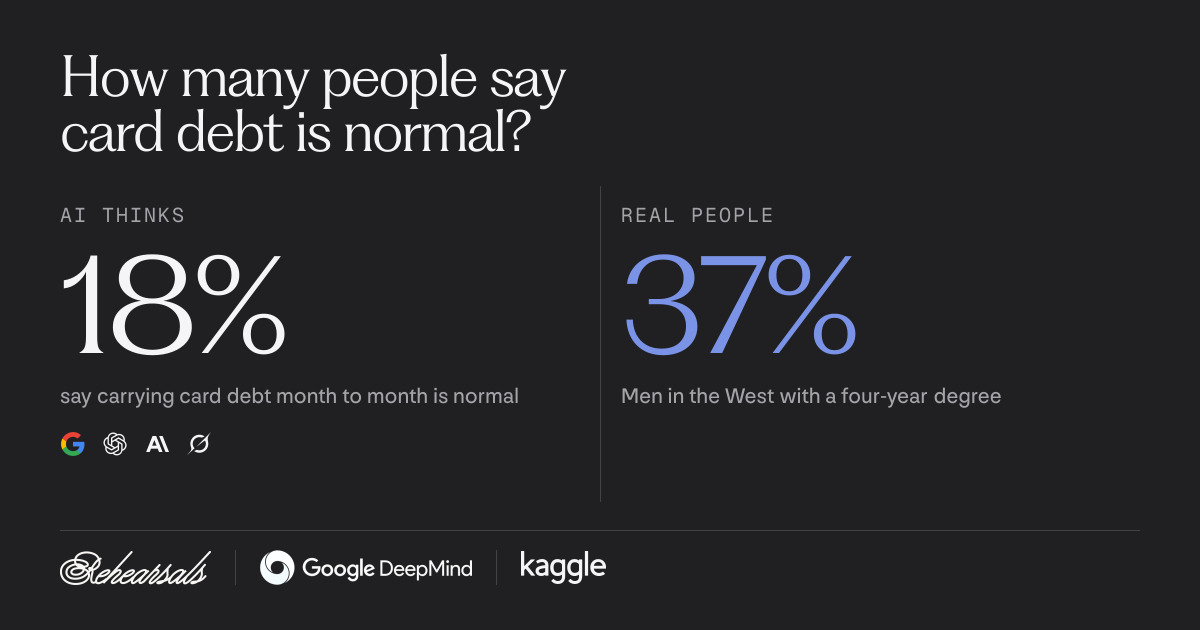
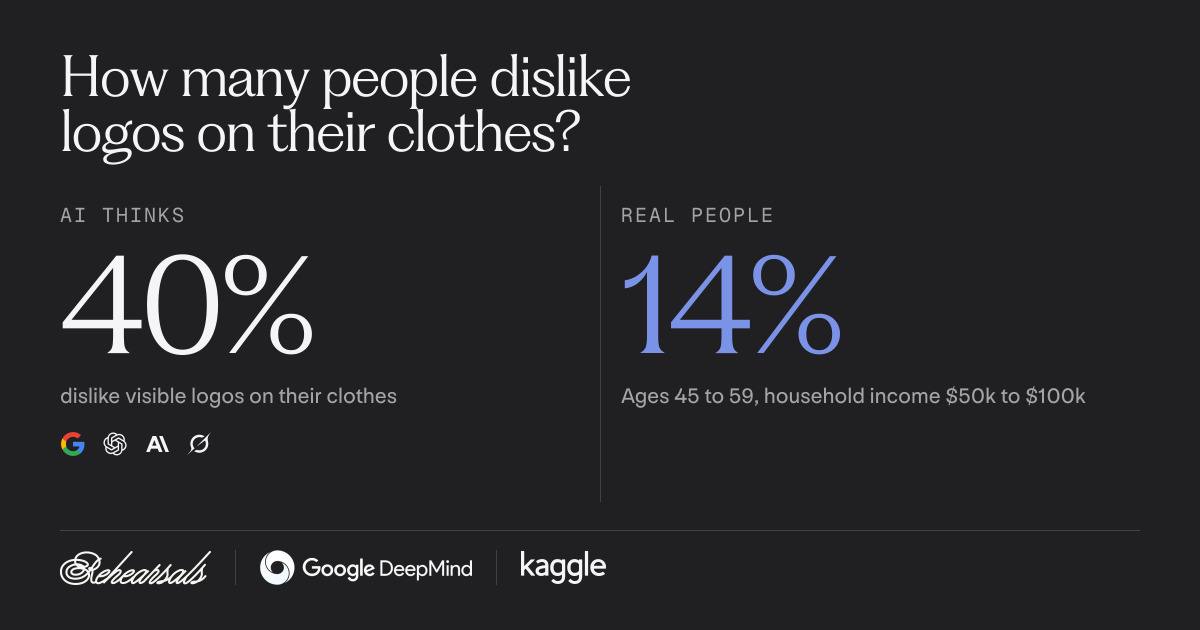
The gaps between the scores show the assumptions AI models make about humanity. AI models think most people are less aware, universally frugal and generally lazier than they really are. A few examples:
- AI thinks most people over 65 don’t watch short form videos. In reality: 80% did last week.
- AI thinks only half of 55 to 64 year olds would keep their plan after a $4 hike. In reality: 70% do.
- AI thinks 30% of parents with toddlers do the cooking. In reality: Around 66%.
- AI thinks 5% of older Midwest shoppers tap their phone to pay. In reality: 25%.
More results, findings and updates are available on the interactive benchmark site: Rehearsals Human Behavior Bench. The benchmark is also hosted on Kaggle so any company or individual can score their latest model.
Rehearsals Engram 1.0
Rehearsals built the Human Behavior Bench as the scorecard for Rehearsals Engram, the company’s internal model, which it is previewing today with select partners. Rehearsals Engram is a large language model that has been trained on hundreds of thousands of hours of video and audio interviews to better understand and predict observed human decision making and stated reasoning, all curated from Rehearsals’ human research platform.
Rehearsals Engram has not been trained on any benchmark content and was trained on a separate set of human data. Rehearsals Engram 1.0 powers the predictions Rehearsals’ customers rely on to make business decisions.
What’s next
This first version of the benchmark is limited to the US and a smaller audience. The next version will include more participants, across four more countries and a broader spectrum of focus areas. Rehearsals expects the new version to launch before the end of 2026.
About Rehearsals
Rehearsals (Deep Prediction Inc.) is an AI consumer research platform that predicts marketing outcomes by simulating AI twins of real people. It is the only simulation platform with its own foundation model, Rehearsals Engram, and its own first-party human panel. Marketing, consumer insights and product teams use Rehearsals to test pricing, messaging, ad creative and product concepts in 30 minutes. Rehearsals is backed by Andreessen Horowitz Speedrun, 25madison, Plug and Play Ventures and Factorial Fund, with angel investors from OpenAI, Google DeepMind and Scale AI. For more information, visit runrehearsals.com.
Disclaimer
The Human Behavior Bench leaderboard results and performance metrics reported were conducted publicly by Rehearsals (Deep Prediction Inc.) and DeepMind using the Kaggle platform. Kaggle allows the general public to see the benchmark data. A portion of the benchmark data is public while most is private to maintain the validity of the benchmark. This release contains forward-looking statements regarding planned product changes and international expansion goals, which are subject to change. All third-party company names, brand logos, and model names, including Google DeepMind, Kaggle, OpenAI, Anthropic, and SpaceXAI, are trademarks of their respective owners, and their inclusion in this release as well as the benchmark webpage does not constitute an endorsement, affiliation, or sponsorship of Rehearsals or its products.
Media Contact
Liam Bolling
CEO, Rehearsals
liam@deepprediction.ai
SOURCE: Rehearsals


